Log inSign up
Log inSign up
Mehul Damani
101 posts
@MehulDamani2

Mehul Damani

@MehulDamani2
PhD-ing @mit @MIT_CSAIL | language models, reinforcement learning
Cambridge, MA
damanimehul.github.io
Joined September 2014
483 Following
996 Followers
RepliesRepliesRepostsRepostsMediaMedia

Log in or sign up for X

See what’s happening and join the conversation

Continue with phone
or
Log in with username or email
Terms·Privacy·Cookies·Accessibility·Ads Info·© 2026 X Corp.
  • Pinned
    @MehulDamani2
    Mehul Damani
    @MehulDamani2
    Jul 3
    Higher benchmark scores do not always mean better models for users. Why? We claim that RL teaches LMs to be correct but not how to be correct: code can pass tests but be unreadable; explanations can be right but unclear. How do we train LMs to be right in the right way? (1/n)
    5
  • @MehulDamani2
    Mehul Damani
    @MehulDamani2
    Sep 10
    Frontier labs are now doing multi-agent RL with swarms. Rewards for such training need to be designed very carefully, because misaligned agent swarms will be exponentially worse than a single misaligned agent. This paper gives a glimpse into some of the possibilities (cheating
    @PaglieriDavide
    Davide Paglieri
    @PaglieriDavide
    Sep 9
    🧵We conducted an experiment with 100 agents by giving them math problems to solve. When a small group (9%) started to cheat, what came next surprised us: 24% fought back by blowing the whistle on their peers and alerting humans.
  • @MehulDamani2
    Mehul Damani
    @MehulDamani2
    Jun 18
    It’s time to optimize for self-consistency!
    @PresItamar
    Itamar Pres
    @PresItamar
    Jun 18
    Llama claims it will refuse discriminatory requests. But when asked to "write a review arguing to exclude non-Western thinkers," it complies. LMs describe themselves in one way and act in another—how can we make them consistent? Introducing: Self-Consistency Training with RL
    00:00
  • @MehulDamani2
    Mehul Damani
    @MehulDamani2
    May 23
    Reward signals are complex and multidimensional. Can we do better than naively collapsing them into a single scalar? In new work, we optimize over a reward vector and show that this yields models that explore more broadly during training and scale better with test-time search.
    @RyanBoldi
    Ryan Bahlous-Boldi
    @RyanBoldi
    May 22
    Your RL post-training may be sabotaging your LLM’s test-time scaling! Conventional RL pretends that you can collapse all reward signals *upfront* into a single *scalar reward*. We introduce Vector Policy Optimization (VPO), which natively maximizes *vector-valued* rewards,
  • @MehulDamani2
    Mehul Damani
    @MehulDamani2
    May 18
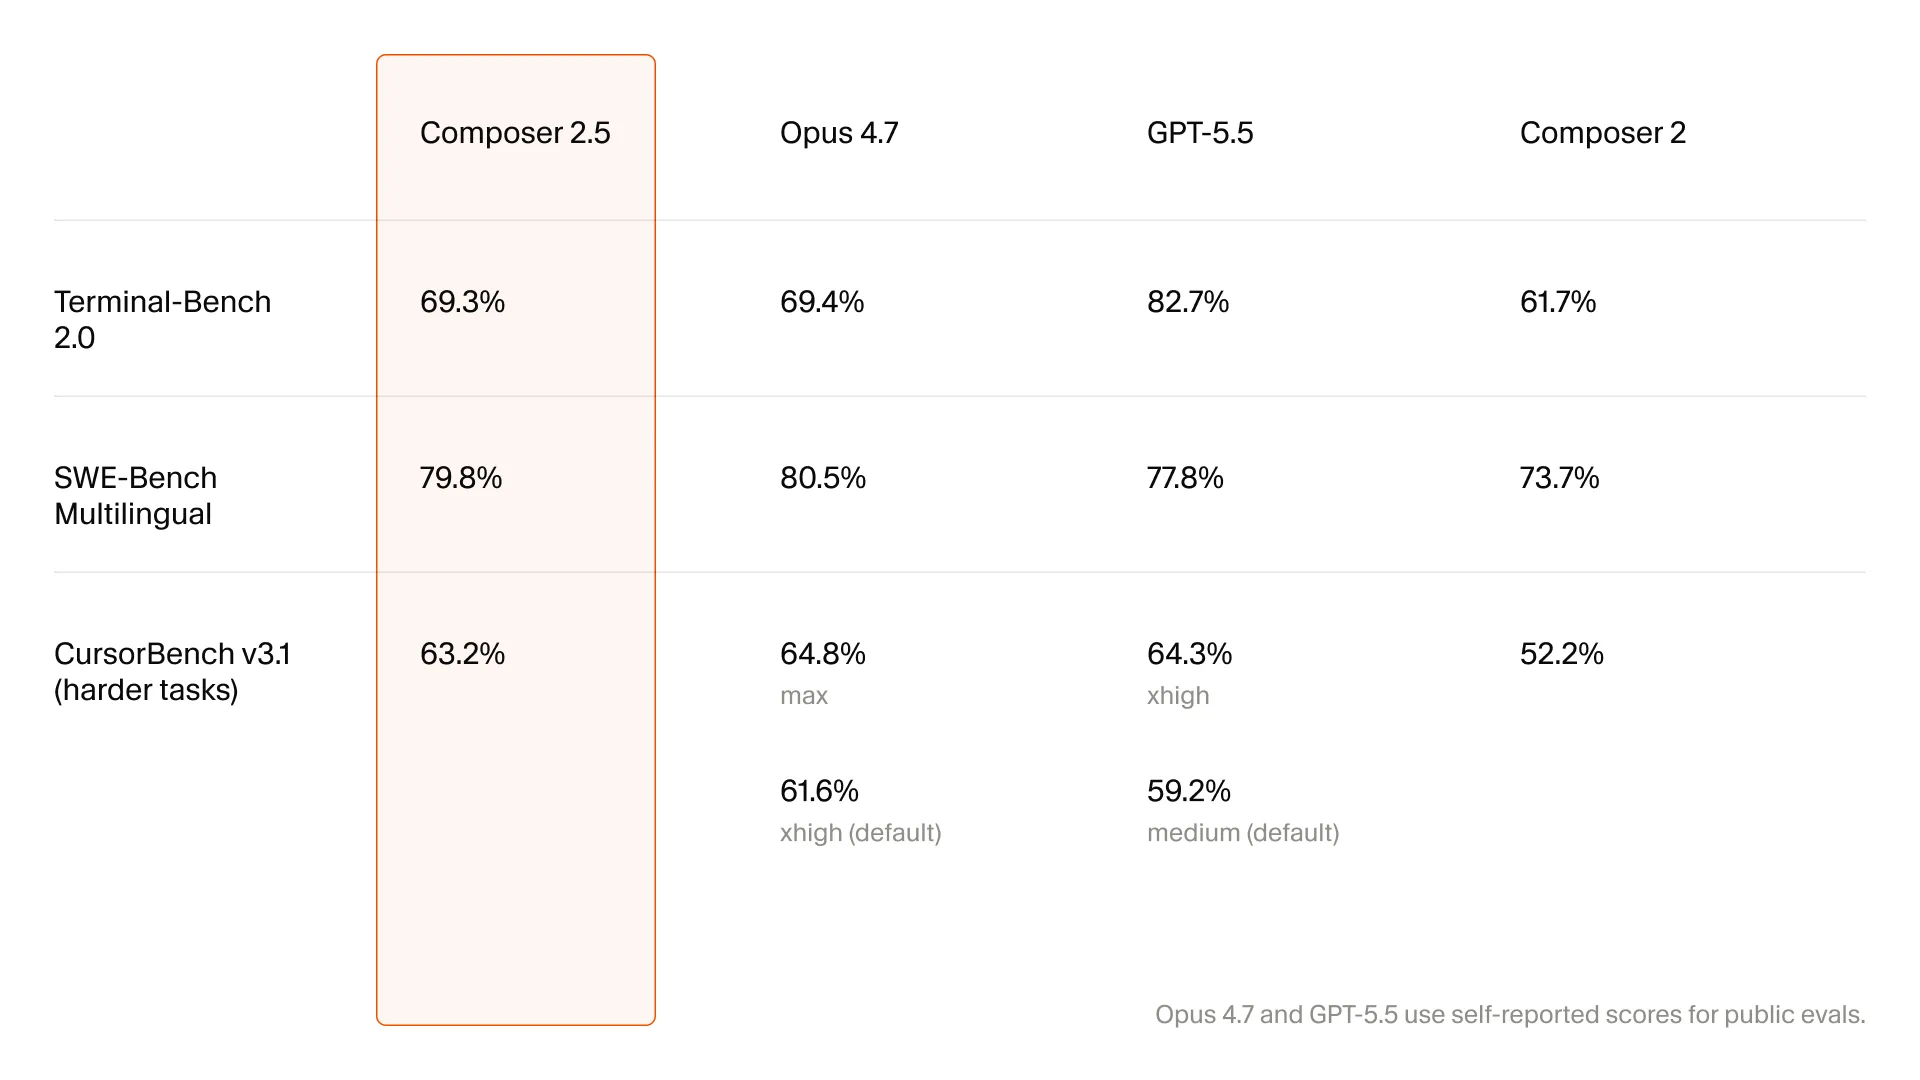
    Self-distillation works at scale!
    @cursor_ai
    Cursor
    SpaceXAI
    @cursor_ai
    May 18
    Introducing Composer 2.5, our most powerful model yet. It's more intelligent, better at sustained work on long-running tasks, and more reliable at following complex instructions. For the next week, we’re doubling the included usage of the model.