Log inSign up
Log inSign up
Han Guo
3,548 posts
Han Guo profile banner
@HanGuo97

Han Guo

@HanGuo97
PhD Student @MIT_CSAIL | Past: @togethercompute @LTIatCMU @MITIBMLab @UNCNLP, @SFResearch, @BaiduResearch | Machine Learning, NLP.
han-guo.info
Joined August 2016
4,503 Following
4,413 Followers
RepliesRepliesRepostsRepostsMediaMedia

Log in or sign up for X

See what’s happening and join the conversation

Continue with phone
or
Log in with username or email
Terms·Privacy·Cookies·Accessibility·Ads Info·ÂĐ 2026 X Corp.
  • @HanGuo97
    Han Guo
    @HanGuo97
    Oct 5
    Can we have 4D linear attention ðŸĪ”
    @osieberling
    Oliver Sieberling @ COLM
    @osieberling
    Oct 4
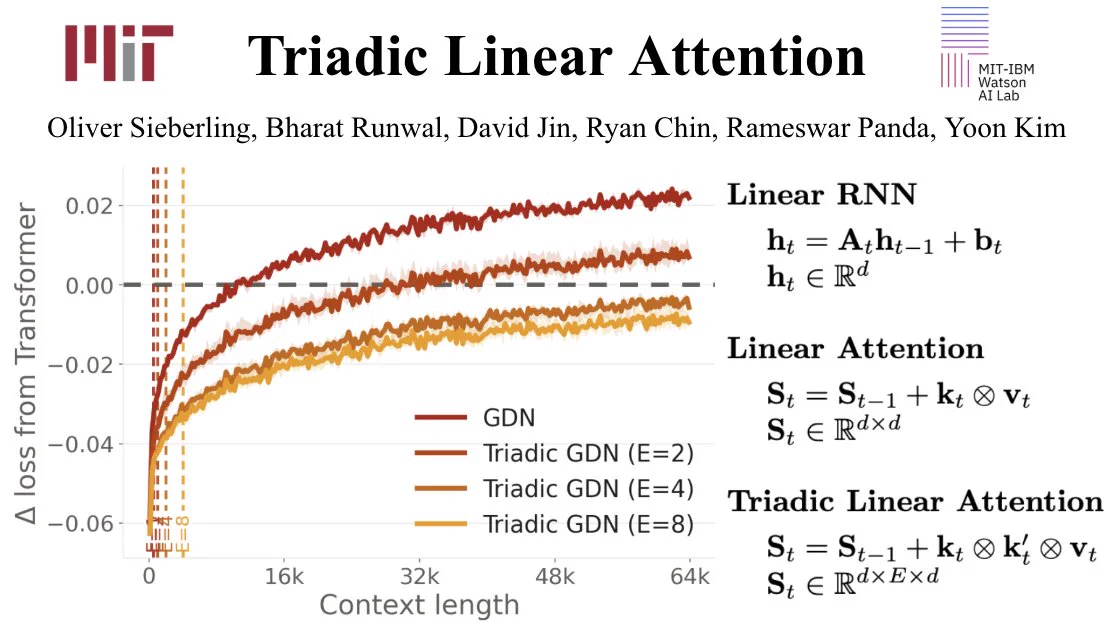
    Linear attention is arguably the most naive RNN, but still massively outperforms traditional RNNs by maintaining a matrix state. So... what if we use a (triadic) outer product of three vectors and maintain a three-dimensional state? Introducing: Triadic Linear Attention ðŸ§ĩ
    1
  • @HanGuo97
    Han Guo
    @HanGuo97
    Sep 30
    Very cool paper!
    @RulinShao
    Rulin Shao
    @RulinShao
    Sep 30
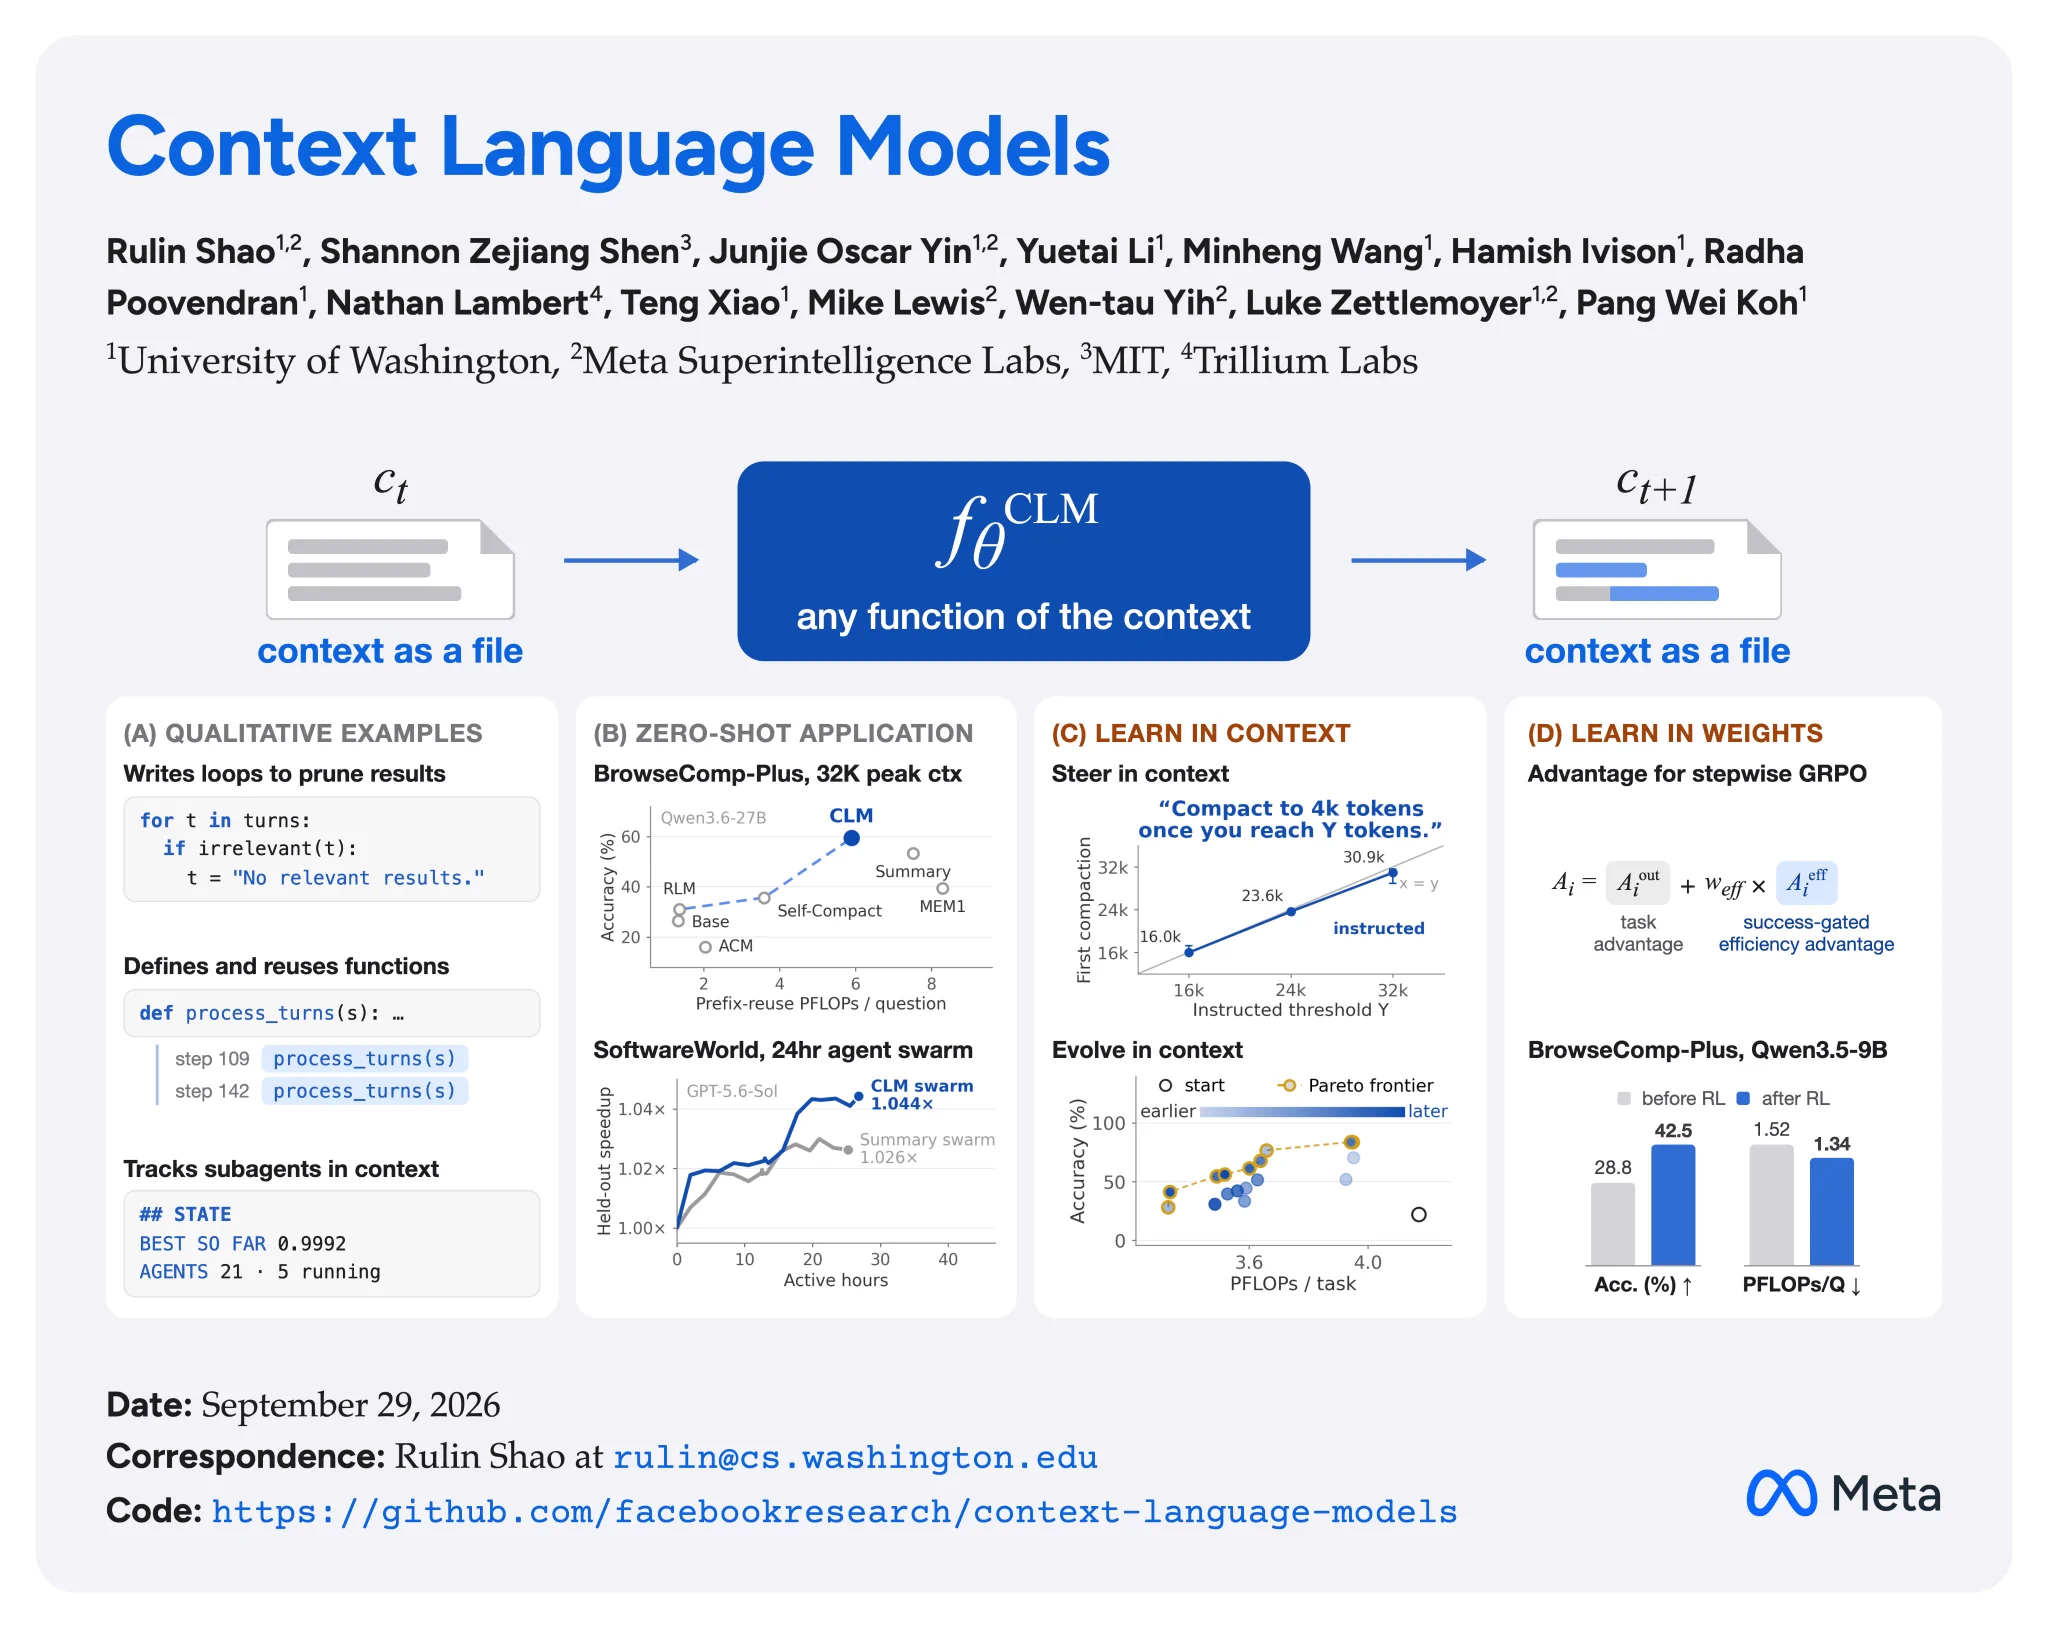
    ‾ïļThe Bitter Lesson for context management: Giving LMs unrestricted control over their context beats human-designed SOTA! Introducing ðŸĐĩContext Language Models (CLMs)ðŸĐĩ - Natively manage their own context - Treat context as a file - Learn policies in CLM weights, no harness
  • @HanGuo97
    Han Guo
    @HanGuo97
    Sep 22
    Pretty cool work! Especially impressive given how heterogenous the computes are ðŸŦĄ
    @MayankMish98
    Mayank Mishra
    @MayankMish98
    Sep 22
    We pretrained a 2.3B MoE (360M active) Hybrid Mamba-2 that lands within a few points of Llama-3.2-3B using <1% of its pretraining FLOPs. No dedicated cluster. The run hopped between H100s, A100s, V100s (yes, V100s) and TPU v5p/v6e on a single codebase. Meet Rigel ðŸ§ĩ
  • @HanGuo97
    Han Guo
    @HanGuo97
    Sep 4
    Time to learn more about Blackwell kernels ðŸĪ”
    @LukeHua34850193
    Luke D. Huang
    @LukeHua34850193
    Sep 4
    First blog! Part 1 of writing speed-of-light GEMM kernels on Blackwell. This part covers basic GPU architecture, CuTeDSL fundamentals, loop tiling/TMA/TMEM, and swizzling. lukehuang33.github.io/blog/b200-matmâ€Ķ
  • @HanGuo97
    Han Guo
    @HanGuo97
    Aug 21
    When I first saw this, it immediately got me excited. This just feels right.
    @jyo_pari
    Jyo Pari
    @jyo_pari
    Aug 20
    In-context continual learning requires models to accumulate experience and reuse it later in the same sequence. But an RNN compresses an ever-growing history into a fixed-size state, where each token gets a single write into memory. We study dynamic compression: letting the
    1