TL;DR: top web search MCP servers for Claude, Cursor, Codex and more
| Server | What it does |
|---|---|
| Firecrawl MCP | Search, scrape, crawl, browser automation, autonomous research agent, and Firecrawl Alexandria data providers |
| WebSearch-MCP | Self-hosted web search with full privacy, no external API required |
| Tavily MCP | Real-time web search and content extraction for AI agents |
| Exa MCP | Web search and page fetching with advanced filters and a rate-limited free plan |
| Brave Search MCP | Independent 40B+ page index with privacy-first web, local, and news search |
After the list, the post covers setup in Claude Code, Claude Desktop, Cursor, and Codex, which vendors ship an official server for Claude Desktop, when Claude Code's built-in WebSearch is enough, and how the built-in tools compare on token usage.
Most AI assistants are frozen at their training cutoff. They can tell you what was true six months ago, but they cannot tell you what changed last week.
Real-time web search MCP servers fix that. They connect your AI coding tools directly to the live web so the model can look things up mid-task, without you having to copy-paste documentation or news articles in manually. They are also becoming the go-to context layer for AI agents: the tool the model calls when its own knowledge runs out.
The catch is that your agent is only as good as the data it retrieves. Search quality has become a real pain point for developers building production agents: shallow snippets and stale results flow directly into degraded model output. The choice of search tool matters more than it might seem.
I have been using MCP servers for web access across Claude Code, Cursor, Codex CLI, and other tools. The ecosystem has grown fast. There are now dedicated servers covering everything from basic Google-style search to full browser automation and autonomous research agents. This post covers the five I have found most worth recommending, with honest notes on setup friction and where each one falls short.
MCP (Model Context Protocol) is the open standard developed by Anthropic for connecting AI assistants to external tools and data sources. Any MCP client (Claude Code, Claude Desktop, Cursor, Codex CLI, VS Code, Windsurf, and more) can connect to these servers without custom integration work. These are the top web search MCP servers for Claude, Cursor, Codex, and any other MCP client I would hand someone starting today. If you're on Claude and weighing the built-in web search tool against external MCP servers, see Anthropic web search alternatives. If you're on Codex, Codex web search with Firecrawl walks through the exact swap from snippet-only defaults to live results.
What are web search MCP servers?
A web search MCP server is an MCP-compatible process that exposes search and retrieval tools to AI assistants. When an AI like Claude calls firecrawl_search or web_search_exa, the server goes out to the web, fetches results, and returns clean text back to the model.
There are two broad types:
- Hosted remote servers: The server runs in the cloud. You connect via a URL with an API key. No local process to manage.
- Local stdio servers: The server runs on your machine, usually started via
npx. It communicates with the AI client over standard input/output.
Most production-grade options are moving toward remote hosted URLs because they are simpler to maintain, easier to update, and work with any client that supports HTTP transport. For a wider view of what the MCP ecosystem covers beyond search, MCP servers for developers maps out tools for code, databases, memory, and more.
One thing worth knowing before evaluating options: many search APIs marketed at AI agents are wrappers around Google or Bing. If your agent already has a Google tool configured, calling a Google-wrapped MCP server will surface the same ten results. This became more pointed after Microsoft retired the classic Bing Search API, and teams that had built on it scrambled for Bing search API alternatives. The servers that differentiate avoid the wrapper problem by building their own data layer. Exa is a search engine with a neural index. Firecrawl is the context API for AI agents, and it searches, scrapes, crawls, and interacts from one install. Both use their own indexes rather than re-ranking the same SERP.
The second dimension is how much the server does after returning results. A 2025 survey on agentic deep research found that standard LLMs using basic keyword search score below 10% on complex multi-hop research benchmarks. Systems built around iterative retrieval (search, reason, search again) score dramatically higher.
The difference is not the search engine. It is whether the tool supports a loop. That is the practical distinction between a search-only MCP server and one with an autonomous research agent built in.
Keyword vs. semantic vs. answer engines
Web search MCP servers fall into three broad categories that shape what your agent actually sees:
| Category | How it works | Best for | Example MCP servers |
|---|---|---|---|
| Keyword search | Matches query terms against indexed pages, ranks by link structure and freshness | Broad coverage, recent news, exact-phrase lookups | Serper (Google), Brave Search, DuckDuckGo |
| Semantic / neural search | Uses embeddings to match query intent, not exact terms | Conceptual queries, research, "find companies like X" | Exa, Firecrawl (for full-page context) |
| Answer engines | Retrieve, synthesize, and return a cited summary in one call | Q&A workflows, when you want text not links | Perplexity, Tavily's advanced mode |
| Full-stack web context | Search + scrape + crawl + interact + Firecrawl Alexandria data providers in one MCP session | Agents that need to reason across sources or act on pages | Firecrawl |
Most production agent stacks combine at least two of these: a broad keyword engine for coverage and a semantic or full-stack option for depth. If you only need one MCP server for search, pick the one that matches the workload the agent runs most often.
1. Firecrawl MCP
Firecrawl MCP is the most capable web data server in this list, covering search, scraping, crawling, browser automation, and an autonomous research agent in a single install, with the most accurate /search we have ever shipped at its core.
Firecrawl started at the deepest part of the stack (extraction) and built the complete workflow from there. It is now the context API for AI agents: Search, Scrape, Parse, Crawl, Map, and Interact in a single API. With default settings the MCP server lists 27 tools on its full profile, more than any other server in this roundup. The extra tools are not padding: each one addresses a distinct step in how agents interact with the web, from discovering URLs on a site to executing multi-step browser interactions to running a fully autonomous research task in the background.
The key distinction from every other server in this list is what happens after the search, inside one MCP session. Firecrawl's server bundles search, scrape, deeper crawl, autonomous research, and browser interact behind the same session, so the agent can follow a lead from ranked URL to clean markdown to a clicked-through page without switching servers. Other servers expose narrower MCP surfaces: Tavily's MCP ships search, extraction, map, and crawl, Exa's ships search variants and page fetching, so multi-step chains still work but route through separate calls or a broader integration outside MCP.
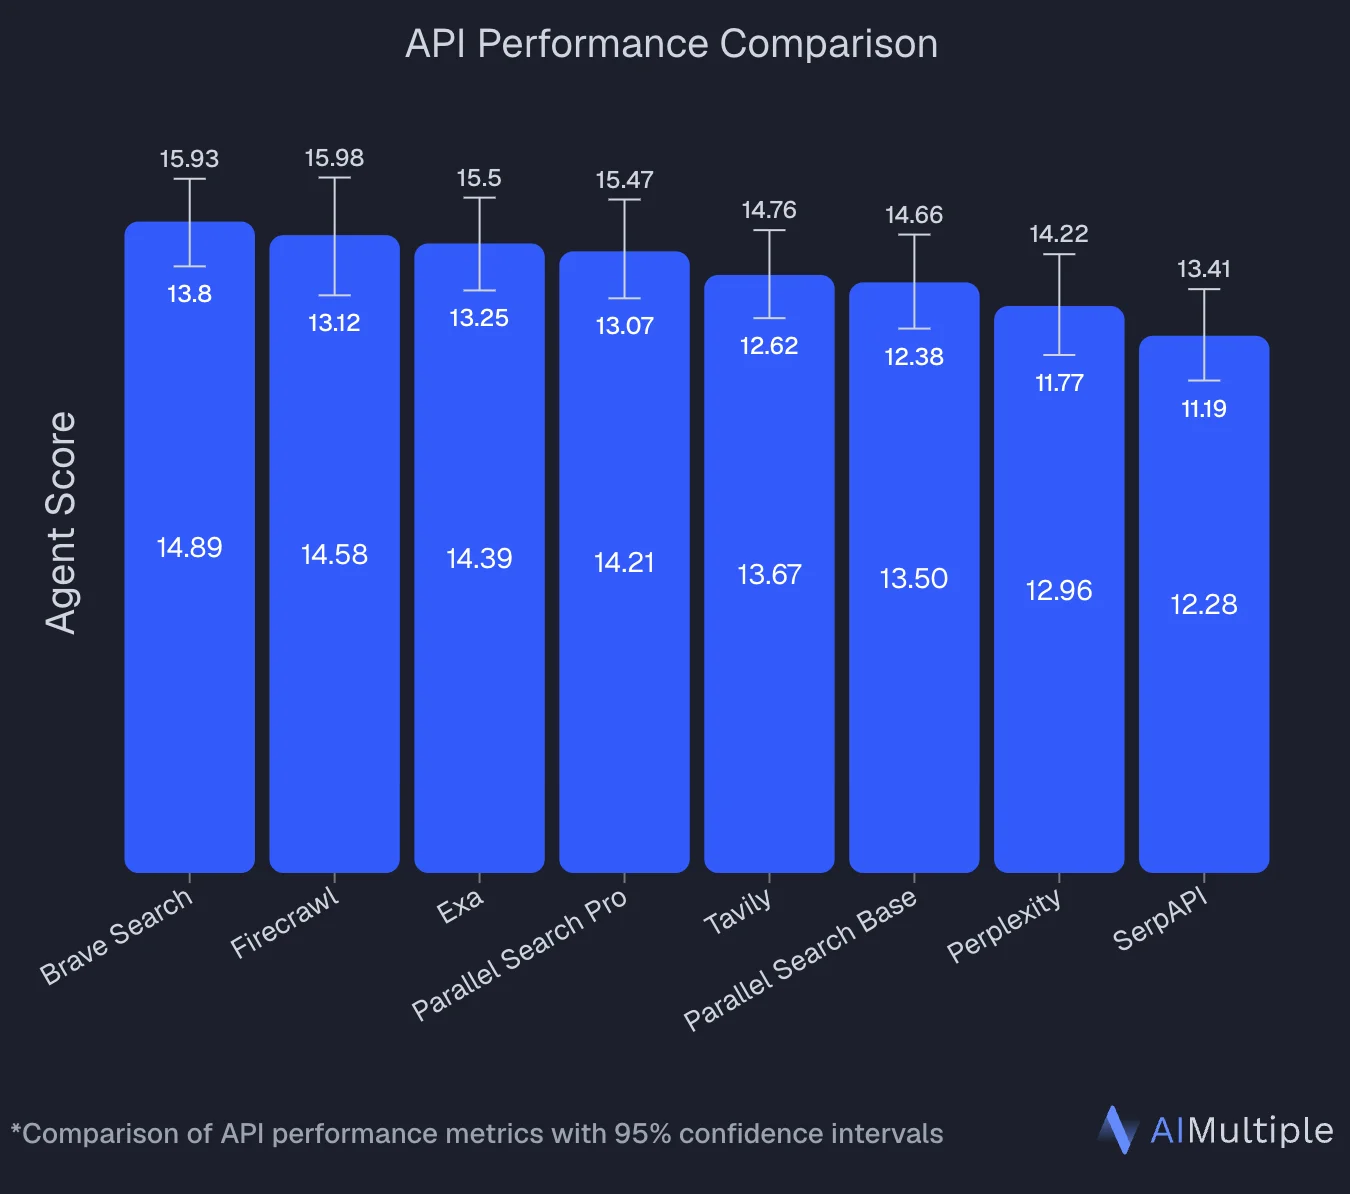
An independent benchmark by AIMultiple that evaluated 8 search APIs across 100 real-world AI/LLM queries ranked Firecrawl second overall with an Agent Score of 14.58, statistically tied with the top performer (Brave Search at 14.89). Firecrawl posted the highest mean relevant score in the benchmark (4.30 out of 5) and performed best on deep content retrieval tasks, the workload that separates full-page extraction from snippet-only search.
A more recent internal eval on SimpleQA (OpenAI's factuality benchmark, 4,326 short fact-seeking questions) put a major upgrade to /search at the top of the pack. A GPT-5.4 agent running with Firecrawl /search and web_fetch scored 94.7%, higher than the same agent paired with any other provider Firecrawl tested (Exa, Parallel) and higher than Claude Sonnet 4.6 with Anthropic's native server-side web search. The upgrade shipped a custom relevance model that returns only the excerpts on each page that answer the query, so agents work with ~10x fewer tokens than processing full pages while getting more accurate context. Live across the API, SDKs, CLI, and MCP with no config changes required.
An independent benchmark also ranked Firecrawl the most token-efficient search-only API for coding agents.
Beyond general web search, Firecrawl also ships two purpose-built indexes reachable through the same MCP install, so a coding or research agent can hit the right source directly instead of ranking through the open web:
- Developer Index: an index of GitHub issues, merged pull requests, repository READMEs, and curated documentation sites, built for coding agents. Filters by
types(doc,issue,pull_request,readme), byreposorsources, and by repository attributes likelanguage,topic,license, andmin_stars. Useful when an agent needs to trace an API contract to the PR that changed it, find the issue where a bug was reported and fixed, or answer from a README passage instead of a Google result. Install as an agent skill withnpx -y firecrawl-cli@latest setup developer-index. - Research Index: an index of roughly 43 million paper abstracts, majority biomedical and life sciences (PubMed, bioRxiv, medRxiv) alongside arXiv for physics, math, and CS. It exposes a research-specific toolset for searching papers, inspecting metadata, reading passage-level full text, and expanding by citations or references. This is the one to reach for on actual literature work rather than
categories: ["research"]on/search, which only restricts the open web to about 14 academic domains. Install as an agent skill withnpx skills add firecrawl/skills@firecrawl-research-index.
Both indexes are providers inside Firecrawl Alexandria, alongside official APIs such as SEC EDGAR and FRED and licensed publishers such as Fiscal.ai and Particle.
The catalogue itself is the argument for choosing Firecrawl here. It includes the Wayback Machine for how a page looked on any past date, Greenhouse job boards for every open role at a company, GitHub, Hugging Face, PyPI, and Stack Exchange for developer questions, Companies House and SEC EDGAR for registries and filings, and 80+ other providers, all reachable from the one search call an agent already makes.
Available tools:
firecrawl_search: Search the web and get back the excerpts that best answer the query. A custom relevance model scores every paragraph, list, and table on each result page and returns only what matters, cutting token cost by roughly 10x compared to processing full pages while topping SimpleQA at 94.7%. Supports time-based filters (qdr:d,qdr:w,qdr:mfor past day/week/month, plus customcdr:1,cd_min:MM/DD/YYYYdate ranges), geographic location targeting, source filters for web, images, or news, andincludeDomains/excludeDomainsrestrictions. It also supports search categories (github,research,pdf), so the same MCP call can search GitHub repos, academic sources (arXiv, Nature, IEEE, PubMed), or PDFs directly, without wiring up separate specialty MCP servers. Query-relevant Highlights come back by default; sethighlights: falsefor raw descriptions instead, or passscrapeOptionsto also get full-page markdown when you need it. Filtering bytypes,repos,language,topic,license, andmin_starsis available over the REST API (api.firecrawl.dev/v2/search/developer); the MCP toolfirecrawl_developer_searchdoes not expose those filters. It ranked #1 overall on the DevDex benchmark at 63.1% Recall@10, so coding agents get the exact PR that fixed a bug or the doc page that answers a how-to instead of a general web result.firecrawl_find_tools: Browse the Firecrawl Alexandria catalogue of 90+ data providers and read a tool's contract (required options, response shape, price in credits) at no cost.firecrawl_searchreturns matching tools when the call includessources: ["alexandria"], andfirecrawl_scraperuns one when given analexandriablock instead of a URL, billed at the tool's listed price. Needs an API key on a team where Firecrawl Alexandria is enabled, so these tools are hidden on the keyless endpoint.firecrawl_scrape: Scrape a single URL into clean markdown or structured JSON. Options include JavaScript rendering with a configurablewaitFordelay, mobile viewport simulation, tag inclusion/exclusion filters, and TLS verification control.firecrawl_map: Discover all indexed URLs on a site before deciding what to scrape. Useful for finding the right page before committing to a full crawl.firecrawl_crawl+firecrawl_check_crawl_status: Asynchronous site crawl with configurable depth (maxDiscoveryDepth), page limits, deduplication, and external link filtering. Returns a job ID immediately; poll for results.firecrawl_agent+firecrawl_agent_status: Autonomous research agent that browses the web independently, follows links, and returns structured results. Useful for open-ended research tasks where you do not know which pages to target in advance.firecrawl_interact+firecrawl_interact_stop: Clicks, form fills, navigation, and dynamic-page extraction in a live browser, starting from a URL or from thescrapeIdof an earlier scrape. Callfirecrawl_interact_stopto release the session.firecrawl_parse: Turn a PDF, document, spreadsheet, or HTML file into text. The hosted server uses a signed upload handoff for files on your machine.firecrawl_monitor_*: Create, run, and inspect recurring monitors that diff a page and send webhook or email notifications when it changes.
Install (Claude Code):
# Keyless: search, scrape, and parse with no account
claude mcp add --transport http firecrawl https://mcp.firecrawl.dev/v2/mcp

# Sign in through the browser for the full tool set, then run /mcp to finish
claude mcp add --transport http firecrawl https://mcp.firecrawl.dev/v2/mcp-oauth

# Local via npx with an API key
claude mcp add firecrawl --env FIRECRAWL_API_KEY=fc-YOUR-API-KEY -- npx -y firecrawl-mcp
Claude Desktop: add the Firecrawl connector from Claude's connectors directory, or go to Customize > Connectors, add a custom connector named firecrawl, and use https://mcp.firecrawl.dev/v2/mcp-oauth as the server URL. The same connector works in Cowork and the Code tab.
Cursor (~/.cursor/mcp.json):
{
  "mcpServers": {
    "firecrawl": {
      "url": "https://mcp.firecrawl.dev/v2/mcp",
      "headers": {
        "Authorization": "Bearer <FIRECRAWL_API_KEY>"
      }
    }
  }
}
Drop the headers block to start keyless. Keep the API key in the header; never put it in the server URL.
Windsurf (./codeium/windsurf/model_config.json):
{
  "mcpServers": {
    "mcp-server-firecrawl": {
      "command": "npx",
      "args": ["-y", "firecrawl-mcp"],
      "env": {
        "FIRECRAWL_API_KEY": "YOUR_API_KEY"
      }
    }
  }
}
Codex CLI:
# Keyless
codex mcp add firecrawl --url https://mcp.firecrawl.dev/v2/mcp

# Sign in for the full tool set
codex mcp add firecrawl --url https://mcp.firecrawl.dev/v2/mcp-oauth
codex mcp login firecrawl
Both commands write the server to ~/.codex/config.toml, which the Codex CLI, IDE extension, and ChatGPT desktop app share.
Codex also supports the Firecrawl CLI skill as an alternative: npx -y firecrawl-cli@latest init --all --browser registers the tools without touching a config file. See the Codex CLI quickstart for the full setup. Codex's built-in web search returns snippets only, and Codex agents can't browse the web without an additional tool, which is exactly what these config blocks add.
For a step-by-step guide to switching Codex from its stale cached default to live results with Firecrawl, see Codex web search with Firecrawl. For a curated list of the best Codex skills worth adding to your Codex CLI workflow, see the best Codex skills guide.
Example prompts:
# Search with full page content
"Search for the latest OpenAI API pricing changes from the past week"

# Search academic sources via research category
"Search research papers about retrieval-augmented generation from arXiv and IEEE"

# Search GitHub via category filter
"Search github for MCP server implementations in TypeScript"

# Scrape and extract structured data
"Scrape https://docs.example.com and extract all endpoint names, methods, and descriptions as JSON"

# Map then crawl
"Map https://example.com/blog and find all posts published in 2026, then crawl the top 5"

# Autonomous research agent
"Research the current state of MCP server adoption across AI coding tools and return a summary with sources"

# Browser interaction
"Go to https://example.com/pricing, switch the billing toggle to annual, and extract every plan's price"

# Autonomous agent for structured research
"Research pricing and availability for the top 5 products on https://shop.example.com and return the results as a table"
Honest take: Firecrawl is the right choice when the task involves more than just looking something up. The firecrawl_search tool returns the query-relevant excerpts from each result page by default, and full page content when you pass scrapeOptions, which matters for agents that need to reason over what they find rather than just cite a URL. The category filters (github, research, pdf) mean one MCP server covers what would otherwise need three: no separate ArXiv MCP, no separate GitHub search, no separate PDF fetcher. The firecrawl_agent tool handles both open-ended research and structured data retrieval: describe a goal and it figures out which pages to visit, follows links, and returns results. I use it when I need competitive research, documentation summarization, or structured data from sites where the page layout is not stable enough to scrape directly. The firecrawl_interact tool is the most underrated: being able to tell Claude "click the Export button and download the CSV" and have it actually do that in a live browser is a different category of capability than search.
The built-in retry logic with exponential backoff and credit usage monitoring are practical touches: the server handles transient rate limit errors automatically and warns you before you run out of credits, which matters for agentic workflows that might run unattended.
Firecrawl is used by 1.25M+ developers and non-developers across 150,000+ companies, and has served 5B+ requests to date. It has reached that scale because it handles the full workflow (search, scrape, crawl, interact) in a single install, on the real web. Builders who need reliable web context for agentic workflows keep coming back to it, and recommend it to others. Firecrawl also sits at the top of most OpenClaw search provider rankings. Peter Steinberger, founder of OpenClaw, put it plainly:
Cons: The full tool surface is overkill if your use case is simply "give Claude access to Google." The keyless endpoint exposes only search, scrape, and parse, which is the whole surface that job needs. Full reference at docs.firecrawl.dev/mcp-server.
2. WebSearch-MCP
WebSearch-MCP is a self-hosted MCP server that gives you web search without sending your queries to any third-party API.
If data privacy is a constraint (internal queries, proprietary research, or compliance requirements around external API calls), WebSearch-MCP is worth the setup effort. It runs entirely on your own infrastructure using Docker Compose, with a companion crawler service handling the actual web requests. The crawler integrates with FlareSolverr, which handles Cloudflare-protected pages.
The server has 32 GitHub stars as of this writing, so it is a smaller community project rather than an enterprise product. That said, the implementation is clean and the single web_search tool covers the search parameters most agents actually need.
web_search: Search the web with control over result count, language, region, included/excluded domains, excluded terms, and result type (all, news, or blogs).- Docker-based crawler service that bundles FlareSolverr to handle website challenges.
API_URLandMAX_SEARCH_RESULTenvironment variables for configuring the server without code changes.- Supports Claude Desktop, Cursor, and Cline as MCP clients.
Install (via Smithery):
npx -y @smithery/cli install @mnhlt/WebSearch-MCP --client claudeSetup the crawler service first (required):
# docker-compose.yml
version: "3.8"
services:
  crawler:
    image: laituanmanh/websearch-crawler:latest
    container_name: websearch-api
    restart: unless-stopped
    ports:
      - "3001:3001"
    environment:
      - NODE_ENV=production
      - PORT=3001
      - LOG_LEVEL=info
      - FLARESOLVERR_URL=http://flaresolverr:8191/v1
    depends_on:
      - flaresolverr
    volumes:
      - crawler_storage:/app/storage
  flaresolverr:
    image: 21hsmw/flaresolverr:nodriver
    container_name: flaresolverr
    restart: unless-stopped
    environment:
      - LOG_LEVEL=info
      - TZ=UTC
volumes:
  crawler_storage:
docker-compose up -dMCP client config:
{
  "mcpServers": {
    "websearch": {
      "command": "npx",
      "args": ["websearch-mcp"],
      "environment": {
        "API_URL": "http://localhost:3001",
        "MAX_SEARCH_RESULT": "5"
      }
    }
  }
}
Example:
"Search for recent TypeScript best practices in news articles"
"Search only on developer.mozilla.org for fetch API documentation"
"Find blog posts about AI agent frameworks from the past month"
Honest take: The self-hosted angle is the whole point. If you are working in a context where all web queries need to stay off third-party infrastructure, this is the only option in this list that delivers that. The bundled FlareSolverr service is a practical touch for pages that show a challenge before their content. The tradeoff is that the setup is non-trivial. You need Docker running, the compose stack healthy, and the MCP server pointed at the right API URL before anything works.
Cons: Not suitable as a quick install. The Docker prerequisite alone rules it out for people who want to get going in under five minutes. A single web_search tool with no scraping or extraction capability means you are getting search snippets, not full page content. The project is small (32 stars), so community support and update frequency are limited compared to the other options here.
Repo: github.com/mnhlt/WebSearch-MCP. Full reference at mcpservers.org/servers/mnhlt/WebSearch-MCP.
3. Tavily MCP
Tavily MCP gives AI agents real-time web search and content extraction, built specifically for the agentic use case and integrated with the major AI orchestration frameworks.
Tavily is a search API designed from the ground up for AI agents rather than humans. The MCP server exposes search, extract, map, and crawl tools, a narrower set than Firecrawl's. Tavily lists partnerships with Amazon Bedrock AgentCore, Microsoft Azure, IBM watsonx Orchestrate, Snowflake, and Databricks, and integrations with LangChain and LlamaIndex.
The remote MCP URL connects to Claude Code with one command, and OAuth handles authentication without an API key in the URL.
tavily-search: Real-time web search with support for general queries, news-focused queries, and domain-specific searches. Configurable result count, search depth (basic or advanced), and optional image/raw content inclusion.tavily-extract: Extract the main content from one or more specific URLs, useful when you already know which pages to read and just need clean text.- Map and crawl tools for listing a site's URLs and reading many of its pages.
- Remote MCP hosted at
mcp.tavily.comwith OAuth authentication support. - Default parameter configuration via environment variable or HTTP header, so you can set global search depth without specifying it per request.
- Works with Cursor, Claude Desktop, Claude Code, Codex CLI, OpenAI, and any MCP-compatible client.
Install (Claude Code, OAuth):
claude mcp add tavily-remote-mcp --transport http https://mcp.tavily.com/mcp/Install (Claude Code, API key in URL):
claude mcp add tavily-remote-mcp -- npx -y mcp-remote https://mcp.tavily.com/mcp/?tavilyApiKey=YOUR_API_KEYLocal install (Claude Desktop):
{
  "mcpServers": {
    "tavily-mcp": {
      "command": "npx",
      "args": ["-y", "tavily-mcp@0.1.3"],
      "env": {
        "TAVILY_API_KEY": "tvly-YOUR_API_KEY"
      }
    }
  }
}
Example:
"Search for recent developments in quantum computing"
"Search for news articles about AI startups from the last 7 days"
"Search for climate change research on nature.com and sciencedirect.com"
"Extract the main content from https://example.com/article"
Honest take: The OAuth flow for Claude Code keeps the API key out of config files. Tavily's platform covers /search, /extract, /crawl, /map, and /research; the MCP server surfaces search, extract, map, and crawl. For research use cases, teams call that endpoint directly rather than through this MCP server.
Cons: The MCP surface (search, extract, map, crawl) is narrower than Firecrawl's. Browser interaction and an autonomous agent aren't exposed here; if your agent needs those inside a single MCP session, you'll need to compose them from Tavily's other endpoints or reach for a different server. API key management is required for most setups outside the OAuth path, and the API key must include the tvly- prefix to be valid.
4. Exa MCP
Exa MCP connects AI assistants to Exa's neural search and page-fetching tools, with a rate-limited free plan and support for a long list of MCP clients.
Exa approaches search differently from traditional keyword engines, positioning itself as a search tool optimized for AI agents rather than human browsing. The MCP server is available at a remote URL (mcp.exa.ai/mcp) and lists support for Cursor, VS Code, Claude Code, Claude Desktop, Codex, OpenCode, Windsurf, Zed, Gemini CLI, Google Antigravity, v0 by Vercel, Warp, Kiro, and Roo Code.
For Claude Desktop specifically, Exa is available as a native Connector. You can add it without touching a config file, just through the Claude Desktop UI.
web_search_exa: Search the web for any topic and get clean, ready-to-use content. Enabled by default.web_fetch_exa: Read a webpage's full content as clean markdown from one or more URLs. Enabled by default.web_search_advanced_exa: Advanced web search with full control over category filters, domain restrictions, date ranges, highlights, summaries, and subpage crawling. Optional, enabled via thetoolsURL parameter.- Remote URL:
https://mcp.exa.ai/mcp, which works without an API key on the free plan. - API key support for production use, passed via
x-api-keyheader or environment variable. - Open source on GitHub at
exa-labs/exa-mcp-server.
Install (Claude Code):
claude mcp add --transport http exa https://mcp.exa.ai/mcpInstall (Cursor / mcp.json):
{
  "mcpServers": {
    "exa": {
      "url": "https://mcp.exa.ai/mcp"
    }
  }
}
Install with API key for production:
{
  "mcpServers": {
    "exa": {
      "url": "https://mcp.exa.ai/mcp",
      "headers": {
        "x-api-key": "YOUR_EXA_API_KEY"
      }
    }
  }
}
Install via npm (for stdio clients):
{
  "mcpServers": {
    "exa": {
      "command": "npx",
      "args": ["-y", "exa-mcp-server"],
      "env": {
        "EXA_API_KEY": "your_api_key"
      }
    }
  }
}
Example:
"Search for recent developments in AI agents and summarize the key trends"
"Find Python examples for implementing OAuth 2.0 authentication"
"Fetch the full content of https://exa.ai and summarize what the company does"
Honest take: The free plan works without an API key, so you add the URL to your MCP config and start. The web_search_advanced_exa tool, when enabled, adds domain restrictions, date ranges, and category filters. For a broader comparison of AI search engines for agents beyond the MCP layer, that post covers Exa alongside Tavily, Perplexity Sonar, and others.
Cons: The free plan has rate limits, and hitting a 429 error without an API key set up is friction you will encounter if you use it heavily. The advanced search tool is opt-in rather than default, which means you need to know it exists and configure the URL parameter to enable it. The tool naming (web_search_exa, web_fetch_exa) is more verbose than necessary.
5. Brave Search MCP
Brave Search MCP is a privacy-first search server backed by an independent index of 40B+ pages, with no Google or Bing backend behind it.
Brave built its own crawler and search index instead of proxying results from Google or Bing, and Firecrawl and Exa run their own indexes too. In AIMultiple's independent benchmark across 100 real-world AI/LLM queries, Brave Search actually placed first with an Agent Score of 14.89, statistically tied with Firecrawl at 14.58. Brave is an option if your agent needs broad keyword coverage without ads or tracking and you would rather not send queries to a Google-wrapped API.
The official Brave Search MCP server is maintained by Brave directly and works with Claude Code, Cursor, Codex CLI, and any other MCP-compatible client. It exposes a small, focused set of tools that map directly onto Brave's public search endpoints.
Available tools:
brave_web_search: General web search with support for pagination, count limits, and freshness filters.brave_local_search: Local business and place search (restaurants, services, points of interest) with location targeting.brave_news_search: News-focused results with recency ranking and per-result publish dates.brave_summarizer: Optional AI-generated summary of top results (available on paid tiers), useful when you want a synthesized answer instead of a link list.- Independent 40B+ page index with no tracking or personalization.
- LLM-optimized response format that returns pre-chunked, context-ready payloads instead of raw SERP snippets.
Install (Claude Code, local stdio):
claude mcp add brave-search --env BRAVE_API_KEY=YOUR_BRAVE_API_KEY -- npx -y @brave/brave-search-mcp-serverInstall (Claude Desktop / Cursor, local stdio):
{
  "mcpServers": {
    "brave-search": {
      "command": "npx",
      "args": ["-y", "@brave/brave-search-mcp-server"],
      "env": {
        "BRAVE_API_KEY": "YOUR_BRAVE_API_KEY"
      }
    }
  }
}
Codex CLI (~/.codex/config.toml):
[mcp_servers.brave-search]
command = "npx"
args = ["-y", "@brave/brave-search-mcp-server"]

[mcp_servers.brave-search.env]
BRAVE_API_KEY = "YOUR_BRAVE_API_KEY"
Example:
"Search Brave for the latest EU AI Act guidance and return the top 5 results"
"Find local coffee shops in San Francisco with high ratings"
"Search recent news about semiconductor export policy from the past week"
"Get a summarized answer about the 2026 changes to Section 174 R&D tax treatment"
Honest take: Brave runs its own index rather than wrapping Google, so it returns a different result set from a Google-backed tool. The brave_local_search and brave_news_search tools cover physical businesses and recent events.
Cons: The index is smaller than Google's, so niche or long-tail queries can miss results that Serper would find. The API is priced per query (around $5 per 1,000 for the Data for AI plan) with no fully-free hosted MCP tier, so it is not a zero-cost drop-in like DuckDuckGo. And the tool surface is search-only: no scraping, no page fetching, no interact, so multi-step research chains still need a companion server like Firecrawl.
For a broader comparison against other independent indexes and Google-backed alternatives, see Brave Search API alternatives.
More web search MCP servers worth knowing
The five above cover the workloads I hit most often, but the ecosystem is wider than that. Six more come up in team stacks worth flagging:
6. Perplexity MCP
The Perplexity MCP server exposes Perplexity's Sonar API, so instead of returning raw results the tool returns a synthesized answer with inline citations. It suits agents whose job is to summarize rather than surface links, such as Q&A assistants, research helpers, and any workflow where you would otherwise spend a second LLM call summarizing search output.
7. Serper MCP
Serper MCP is a Google Search wrapper with organic, news, image, and Shopping results, plus zip-code-level geotargeting. It gives an agent Google's index without setting up a Custom Search Engine. Free tier covers 2,500 queries. Worth knowing: if you are already using Google-backed search elsewhere, this MCP will surface the same results.
8. Jina AI MCP
Jina's MCP server is a URL reader, not a search engine. You hand it a link and it returns clean, boilerplate-free text ready for the model. Useful as a lightweight companion when your agent already knows which pages to read and just needs the content ingested cleanly.
9. Linkup MCP
Linkup MCP combines web query execution and page fetching in a single MCP call, so the agent gets ranked results with body text rather than just a link list. Sits between Serper (search only) and Firecrawl (full stack) in scope.
10. Kagi MCP
The Kagi MCP server surfaces Kagi's ad-free, ranking-forward search results plus its Universal Summarizer and FastGPT tools. It requires an active Kagi developer plan.
11. DuckDuckGo MCP
DuckDuckGo MCP is free, key-free, and configuration-free, and it adds web search to an MCP client without a signup step, at modest rate limits.
How do you add a web search MCP server to Claude Code, Claude Desktop, Cursor and Codex?
Adding a web search MCP server to a coding agent means registering the server's URL or local command in that agent's MCP configuration. Claude Code and Codex take one terminal command, Cursor reads an mcp.json file, and Claude Desktop adds remote servers as connectors. After that, the agent can call the server's search tool next to its built-in web tool.
| Coding agent | Where MCP servers are configured | Add Firecrawl MCP (keyless) | Built-in web tool |
|---|---|---|---|
| Claude Code | ~/.claude.json, or .mcp.json in the project | claude mcp add --transport http firecrawl https://mcp.firecrawl.dev/v2/mcp | WebSearch (titles and URLs) and WebFetch |
| Claude Desktop | Customize > Connectors | Firecrawl connector in Claude's connectors directory | Web search and web fetch |
| Cursor | ~/.cursor/mcp.json, or .cursor/mcp.json in the project | {"mcpServers": {"firecrawl": {"url": "https://mcp.firecrawl.dev/v2/mcp"}}} | The agent's Web tool |
| Codex | ~/.codex/config.toml, or .codex/config.toml in a trusted project | codex mcp add firecrawl --url https://mcp.firecrawl.dev/v2/mcp | web_search (cached by default) |
Sources: the Claude Code, Cursor, Codex, and Firecrawl MCP docs, checked Oct 21, 2026. Every server in this list follows the same pattern; only the name, URL, and key change.
How do I add web search to Claude Code through MCP?
Claude Code adds a web search MCP server with one claude mcp add command that names the server, sets the HTTP transport, and points at the server's URL. Firecrawl's hosted endpoint works without an account for search, scrape, and parse, and the sign-in endpoint opens a browser and unlocks the full Firecrawl tool set.
claude mcp add --transport http firecrawl https://mcp.firecrawl.dev/v2/mcpRun /mcp inside Claude Code to check that firecrawl is connected. A keyless connection lists firecrawl_search, firecrawl_scrape, and firecrawl_parse. Then ask for something that changed after the model's training cutoff:
Use Firecrawl to search for the latest Next.js release notes and summarize the sources.The Claude Code quickstart covers the sign-in path and project-scoped servers.
How do I add web search to Claude and Claude Desktop?
Claude and Claude Desktop add a web search MCP server as a connector. Firecrawl is listed in Claude's connectors directory, so you click Connect, sign in to Firecrawl in the browser, and pick a team, with no config file to edit. The Firecrawl connector then works in chat, Cowork, and the Desktop Code tab.
- Open the Firecrawl connector, or go to Customize > Connectors in Claude Desktop and search for Firecrawl.
- Click Connect, sign in to Firecrawl, and approve a team. On Team or Enterprise plans, an organization Owner may need to allow the connector first.
- In a chat, open the + menu, go to Connectors, and check that Firecrawl is on.
Local servers in claude_desktop_config.json still work in chat, but they don't reach Cowork, so the connector is the better default. The Claude Desktop guide covers custom connectors.
How do I give Cursor a web search tool?
Cursor gets a web search tool from any MCP server added on its Customize page or in an mcp.json file. A global file in your home directory makes the tool available in every project, and a file in the project's .cursor folder scopes it to one repository. Cursor's agent then calls the server's search tool alongside its own Web tool.
{
  "mcpServers": {
    "firecrawl": {
      "url": "https://mcp.firecrawl.dev/v2/mcp"
    }
  }
}
That entry starts keyless. Add an Authorization: Bearer <FIRECRAWL_API_KEY> header for the full tool set, or point the URL at https://mcp.firecrawl.dev/v2/mcp-oauth to sign in through the browser. How to set up Firecrawl MCP in Cursor walks through verification and eight everyday workflows.
How do I give OpenAI Codex better web search than its built-in tool?
Codex gets better web search from an MCP server added next to its built-in web search tool, which serves results from a cache unless you switch it to live mode. One codex mcp add command registers Firecrawl, and the setting is shared by the Codex CLI, the IDE extension, and the ChatGPT desktop app.
codex mcp add firecrawl --url https://mcp.firecrawl.dev/v2/mcpTo leave all searching to the MCP server, turn the built-in tool off in ~/.codex/config.toml:
web_search = "disabled" # other modes: "cached" (default), "indexed", "live"Codex web search vs Firecrawl compares the two in detail, including a full config with retries.
Which web search APIs ship an official MCP server for Claude Desktop?
Firecrawl, Brave Search, Tavily, and Exa each maintain an official MCP server that works with Claude Desktop. They differ in setup. Firecrawl connects from Claude's connectors directory with a browser sign-in, Tavily and Exa host remote servers, and Brave's server runs locally with an API key. Claude Desktop on third-party model providers also bundles a search server with Brave, Tavily, and Exa as presets.
| Search API | Official MCP server repo | Claude Desktop setup | Account needed |
|---|---|---|---|
| Firecrawl | firecrawl/firecrawl-mcp-server | Connector in Claude's directory, or custom connector https://mcp.firecrawl.dev/v2/mcp-oauth | No: keyless endpoint for search, scrape, parse |
| Brave Search | brave/brave-search-mcp-server | Local npx or Docker entry in claude_desktop_config.json | Yes: Brave Search API key |
| Tavily | tavily-ai/tavily-mcp | Remote server at https://mcp.tavily.com/mcp | Yes: OAuth sign-in or API key |
| Exa | exa-labs/exa-mcp-server | Remote server at https://mcp.exa.ai/mcp, or the Claude plugin | No: anonymous use is rate limited |
Sources: each vendor's MCP server README and the Firecrawl docs, checked Oct 21, 2026.
On Claude Desktop with Amazon Bedrock, Google Cloud, Microsoft Foundry, or a gateway as the model provider, Anthropic's docs describe a bundled web search server whose preset providers are Brave, Tavily, and Exa. Any other server, Firecrawl included, connects there through the remote search MCP option.
Is Claude Code's built-in WebSearch good enough, or should you add a web search MCP server?
Claude Code's built-in WebSearch is good enough for quick lookups that need a few links, because it returns result titles and URLs and needs no setup. A web search MCP server is worth adding when the agent needs page content in the same call, a different search provider, search on Amazon Bedrock, or tools beyond search such as scraping and crawling.
Claude Code's tools reference describes the split. WebSearch runs a query against Anthropic's web search backend, may issue up to eight backend searches per call, and returns titles and URLs without opening the pages. To read a result, Claude follows up with WebFetch, which converts the page to Markdown and runs a prompt against it in a separate model call. Claude receives only that call's answer, which the docs describe as "lossy by design". The same docs say the search backend is not configurable and point to an MCP server for anyone who wants a different provider.
| Tool | What a call returns | Change the provider? | Limits worth knowing |
|---|---|---|---|
Claude Code WebSearch | Result titles and URLs, no page content | No | 200 calls per interactive session by default; not on Amazon Bedrock |
Claude Code WebFetch | A separate model's answer about the page, reading up to 100,000 characters | No | Lossy by design; responses cached for 15 minutes |
Codex web_search | Results from OpenAI's web search cache by default; live fetches the latest | No; modes are cached, indexed, live, disabled | Cached results can trail the live web |
| Cursor Web tool | Web search results for queries the agent writes | No setting documented | Built into the agent |
Firecrawl MCP firecrawl_search | Ranked results with query-relevant excerpts; full Markdown with scrapeOptions | It is the provider | Keyless use is rate limited; full tools need sign-in or a key |
Sources: Claude Code tools reference, Codex config docs, and Cursor agent docs, checked Oct 21, 2026.
How do built-in web tools compare with a search MCP server on token usage?
Built-in web tools in coding agents keep search results small but push page reading into extra calls, while a search MCP server that returns query-relevant excerpts puts the useful text into one result. Token cost depends on how many search and fetch calls a task needs and how much page text each call returns to the main model.
Claude Code's WebSearch returns only titles and URLs, so every page Claude reads costs a WebFetch call and a separate model pass over up to 100,000 characters. That keeps the main context small, but details the extraction prompt didn't ask for never reach Claude, and a second fetch costs another pass. Codex's cached web_search returns results without opening pages. Firecrawl's firecrawl_search scores the paragraphs, lists, and tables on each result page and returns the excerpts that answer the query. In Firecrawl's July 2026 SimpleQA eval that meant about 10x fewer tokens than processing full pages.
Independent data on coding agents points the same way. Openbenchmarks ran the same coding agent on 100 documentation tickets with one search API at a time, three runs per ticket, and ranked each configuration by task completion per 1,000 tokens (updated Sep 26, 2026):
| Openbenchmarks board | Firecrawl task completion | Median tokens per task | Completion per 1,000 tokens | Firecrawl rank |
|---|---|---|---|---|
| Search only | 70.3% | 7,456 | 9.43 | 1 of 5 listed |
| Search and page fetch | 76.0% | 17,379 | 4.37 | 2 of 7 listed |
Neither board measured the built-in tools in Claude Code, Codex, or Cursor, so the comparison with them above is based on how each tool works.
Building the top web search MCP servers into your workflow
The servers in this list are not mutually exclusive. For most AI engineering workflows, Firecrawl covers both quick lookups and deep web tasks from one install. Tavily is an option for teams already running LangChain or LlamaIndex, where it has integrations. WebSearch-MCP is the right call when sending queries to external APIs is not an option.
Narrower-scoped MCP servers (Tavily, Exa, Brave Search, WebSearch-MCP) are good for information retrieval: answering questions, finding documentation, pulling recent news. Tavily's MCP adds extraction, map, and crawl alongside search, and its platform exposes a research endpoint outside MCP. Brave brings an independent index for teams that want to avoid Google-wrapped results. If your agent mostly asks questions, any of these works. For the wider picture of search tools for AI agents outside the MCP layer, the dedicated roundup covers Serper, SerpAPI, and other search APIs alongside these MCP servers.
If the task involves multiple unknowns, uncertain starting points, or synthesis across sources, the iterative approach matters. The research on agentic deep research describes this as "autonomous reasoning, iterative retrieval, and information synthesis in a dynamic feedback loop", which maps directly to firecrawl_agent and does not describe what a single-pass search API does. If it needs to act on web data, Firecrawl is the right tool.
For a broader comparison of AI search engines for agents beyond the MCP layer, that post covers Tavily, Exa, Perplexity Sonar, and others in detail. For teams that need dedicated deep research APIs for multi-step agentic workflows, that post covers tools built specifically for autonomous research at scale.
Cost is a practical consideration that comes up constantly in developer discussions. Exa's free-tier remote URL requires no API key. WebSearch-MCP has no per-query cost once your Docker stack is running. Firecrawl and Tavily both have free tiers but shift to usage-based pricing as volume grows.
All five servers implement the open MCP standard, so installing one today does not lock you out of switching later. Most MCP clients support multiple servers simultaneously, so you can run Firecrawl alongside Exa and Brave and let the agent choose based on what the task requires.
For more on how AI agents use web data, the posts on building an AI research agent with Firecrawl and how MCP compares to other agent protocols cover the broader ecosystem well. The Firecrawl MCP server docs are the fastest place to get running if you want a single install that covers all the use cases above.
Frequently Asked Questions
What is a web search MCP server?
A web search MCP server is a Model Context Protocol server that gives AI assistants like Claude real-time access to the web. Instead of relying on training data, the AI can query live web pages, news, and search results directly during a conversation or agentic task.
Do web search MCP servers require an API key?
Most use one. Tavily and Exa use API keys tied to their respective services, and Firecrawl supports an API key too but also lets you start without one, then add a key for higher rate limits. WebSearch-MCP goes furthest: it is self-hosted and does not require an external API key, but it does require you to run your own Docker-based crawler service.
Which web search MCP server works with Claude Code?
All five servers listed here work with Claude Code. Firecrawl, Tavily, and Exa host remote MCP servers over HTTP, so a single claude mcp add command connects them. Brave Search's official server runs locally through npx with a Brave API key. WebSearch-MCP uses stdio transport and requires the local crawler service to be running first.
Can I use these MCP servers with Cursor, Codex, or VS Code?
Yes. Firecrawl, Tavily, and Exa all support Cursor, Codex CLI, and VS Code. For Codex CLI you add the server in ~/.codex/config.toml (remote URL or local via npx). Exa also works with Windsurf, Zed, Gemini CLI, [Google Antigravity](https://www.firecrawl.dev/blog/antigravity-skills), v0 by Vercel, Warp, Kiro, and Roo Code. WebSearch-MCP works with Cursor, Claude Desktop, and Cline.
What is the Firecrawl MCP server?
The Firecrawl MCP server exposes tools for web search, scraping, document parsing, crawling, site mapping, browser interaction, page monitoring, and an autonomous research agent. With default settings the full profile lists 27 tools, and the hosted keyless endpoint lists three (search, scrape, and parse). It runs as a hosted remote URL or a local npx process and works with Claude Code, Claude Desktop, Cursor, Codex, VS Code, Windsurf, and n8n.
Is there a free web search MCP server?
Yes, several. Firecrawl has a keyless mode at https://mcp.firecrawl.dev/v2/mcp that exposes Search, Scrape, and Parse with no account, within a daily limit per IP address. To use it, add that URL as a remote MCP server in your client, for example with claude mcp add --transport http firecrawl https://mcp.firecrawl.dev/v2/mcp in Claude Code or codex mcp add firecrawl --url https://mcp.firecrawl.dev/v2/mcp in Codex, then restart the client and check that firecrawl_search, firecrawl_scrape, and firecrawl_parse appear. The steps for other clients are at https://docs.firecrawl.dev/mcp-server/keyless#try-keyless. Exa's MCP also works without an API key, at lower rate limits. WebSearch-MCP is entirely free and self-hosted. Tavily has a free tier but requires account registration.
What is the difference between Tavily MCP and Exa MCP?
Tavily MCP provides search, extract, map, and crawl tools, with integrations for LangChain, LlamaIndex, and enterprise platforms. Exa MCP enables web search and page fetching by default, with an optional advanced search tool for category filters, date ranges, and domain restrictions, and it installs from the Claude plugin marketplace.
Can I self-host a web search MCP server?
Yes. WebSearch-MCP is fully self-hosted using Docker Compose. Firecrawl also supports self-hosted deployments for both the MCP server and the underlying scraping infrastructure.
Does the choice of web search MCP server affect my agent's output quality?
Yes, significantly. Research on agentic information retrieval has found that standard LLMs using basic keyword search score below 10% on complex multi-hop research benchmarks, while systems built around iterative retrieval (where the agent searches, reasons over results, and searches again) score dramatically higher. The search tool is the foundation your agent reasons on, so shallow snippets or stale results flow directly into lower-quality output.
Are most web search MCP servers just wrappers around Google or Bing?
Many are, which is worth knowing before you choose. If your agent already has a Google tool configured, calling a Google-wrapped MCP server will return the same results. Exa uses its own neural search index optimized for AI agents, and Firecrawl retrieves full page content rather than re-ranking standard search results. WebSearch-MCP runs its own crawler infrastructure. Tavily crawls independently across multiple sources rather than proxying a single engine.
Which web search MCP server is best for deep research versus quick lookups?
For quick lookups (answering a question, finding documentation, pulling recent news), firecrawl_search returns the relevant excerpts from each result in one call, and Exa and Tavily also offer search tools for this. For deep research tasks involving multiple unknowns, uncertain starting points, or synthesis across many sources, Firecrawl's autonomous research agent (firecrawl_agent) is the better fit. It follows links, reasons over what it finds, and iterates until it has a complete answer, closer to the agentic deep research paradigm than a single-pass search tool.
What is the difference between keyword search, semantic search, and answer engines in MCP servers?
Keyword search MCP servers (Serper for Google, Brave, DuckDuckGo) match query terms against indexed pages and rank by link structure. Semantic or neural search MCP servers (Exa, Firecrawl for full-page context) use embeddings to match the intent of the query, so 'find AI startups doing hardware in NYC' returns relevant companies rather than pages containing those exact words. Answer engines (Perplexity, Tavily's advanced mode) go one step further and return a synthesized, cited summary instead of a list of results. Most production agent stacks use a mix.
Which web search MCP servers work without an API key?
Exa's remote MCP URL works without an API key on the free tier (with rate limits). DuckDuckGo MCP is completely key-free. WebSearch-MCP is self-hosted so there is no external key to manage, though you do need to run the Docker crawler. Firecrawl also offers a keyless mode at https://mcp.firecrawl.dev/v2/mcp exposing Search, Scrape, and Parse rate-limited per IP. Perplexity, Tavily, Serper, Kagi, Linkup, and Brave all require API keys.
Which web search MCP server is best for privacy-focused use cases?
Kagi MCP (ad-free ranking with a paid subscription that funds the search), Brave Search MCP (independent index, no tracking), and WebSearch-MCP (self-hosted, queries never leave your infrastructure) are built around privacy. DuckDuckGo MCP is another privacy-friendly free choice for lightweight lookups. For enterprise teams with strict data handling requirements, Firecrawl's /search endpoint offers Zero Data Retention (ZDR) modes (end-to-end or anonymized) via the enterprise parameter, so queries and results are never stored server-side. Which one fits depends on whether you want no third party at all (WebSearch-MCP), a privacy-forward hosted engine (Brave, Kagi), a compliance-grade contract (Firecrawl ZDR), or just no user tracking (DuckDuckGo).
Is there a search MCP server that returns citations and sources rather than links?
Yes. Perplexity MCP returns a synthesized answer with inline citations sourced from the web. Tavily's advanced search mode also surfaces sources alongside the response. If you need cited output but also want raw page content available, pairing Firecrawl (for scraping the cited pages) with one of these answer engines is a common pattern.
Which Firecrawl MCP tools expose Firecrawl Alexandria?
Three. firecrawl_search returns matching data tools in a tools array when the call includes alexandria in sources. firecrawl_find_tools browses the Firecrawl Alexandria catalogue and reads a tool's contract, including required options, response shape, and price in credits. firecrawl_scrape runs a tool when given an alexandria block (provider, capability, options) instead of a URL, billed at the listed price. Discovery through the first two is free.
Does Firecrawl Alexandria work on the keyless Firecrawl MCP endpoint?
No. Firecrawl Alexandria needs an API key on a team where it is enabled, and the hosted keyless endpoint exposes only search, scrape, and parse. Connect with a key, or use the search-only endpoint, to get firecrawl_find_tools and Firecrawl Alexandria execution.
How many searches can Claude Code's built-in WebSearch run in one session?
An interactive Claude Code session allows 200 WebSearch calls by default, shared by the main conversation and any subagents. On recent versions the allowance refills at about 100 calls per hour, and the CLAUDE_CODE_MAX_WEB_SEARCHES_PER_SESSION environment variable raises the cap. The limit applies to the built-in WebSearch tool, not to search tools that come from an MCP server.
Does Claude Code's WebSearch work on Amazon Bedrock?
No. Amazon Bedrock doesn't expose Anthropic's server-side web search tool, so Claude Code sessions on Bedrock have no built-in WebSearch. It works on the Claude API, Claude Platform on AWS, Microsoft Foundry, and Google Cloud's Agent Platform with recent models. A web search MCP server works the same on every provider because it runs outside the model call.
Can a coding agent use its built-in web search and a search MCP server at the same time?
Yes. Claude Code, Codex, and Cursor keep their built-in web tools when you add an MCP server, and the model picks a tool for each step from the tool descriptions. To make the agent use the MCP server, turn the built-in tool off: add WebSearch to the deny list in Claude Code permissions, or set web_search to disabled in the Codex config file.
Do I need a Firecrawl account to add web search to Claude Code?
No. The hosted keyless Firecrawl MCP endpoint connects without an account or API key and exposes search, scrape, and parse within daily limits. Signing in through the browser or adding an API key unlocks the full tool set and higher limits on your team's plan.