Claude Opus 4.8: “a modest but tangible improvement”
28th May 2026
Anthropic shipped Claude Opus 4.8 today. My favourite thing about it is this note in the release announcement:
Users will find Opus 4.8 to be a modest but tangible improvement on its predecessor. There’s still more to be done: we’re working on developing and releasing models that provide many of the same capabilities as Opus at a lower cost.
It’s so refreshing to see an AI lab honestly describe a release as a minor incremental improvement over the previous model!
Honesty seems to be a theme. Here’s my other favorite note from that announcement:
One of the most prominent improvements in Opus 4.8 is its honesty. We train all our models to be honest---for instance, to avoid making claims that they can’t support. But a general problem with AI models is that they sometimes jump to conclusions, confidently claiming to have made progress in their work despite the evidence being thin. Early testers report that Opus 4.8 is more likely to flag uncertainties about its work and less likely to make unsupported claims. This is borne out in our evaluations, which show that Opus 4.8 is around four times less likely than its predecessor to allow flaws in code it has written to pass unremarked.
That linked system card includes the following:
Claude Opus 4.8 had the lowest incorrect-rate of the six models on every benchmark—the most direct measure of factual hallucination. It achieved this mainly by abstaining on questions about which it was uncertain rather than by answering more questions correctly.
Model characteristics
Not much has changed since 4.7.
It’s priced the same as Opus 4.5/4.6/4.7—$5/million input and $25 per million output. “Fast mode” is twice that price, which is a significant reduction from their previous models—fast mode on 4.6/4.7 remains at $30/$150. Note that fast mode is only available to organizations that are part of the research preview, “Contact your account manager to request access”.
Both the reliable knowledge cutoff and the training data cutoff are January 2026, the same as for 4.7.
The context window is still 1,000,000 tokens, and the max output is 128,000 tokens.
The What’s new in Claude Opus 4.8 document has some of the more interesting details. These caught my eye:
Mid-conversation system messages. Claude Opus 4.8 accepts
role: "system"messages immediately after a user turn in themessagesarray (subject to placement rules). This lets you append updated instructions later in a long-running conversation without restating the full system prompt, which preserves prompt cache hits on the earlier turns and reduces input cost on agentic loops.
See also this update to the Anthropic Python SDK. Being able to steer the system prompt mid-conversation sounds really powerful. I was worried this would be incompatible with the abstraction provided by my own LLM library, which expects a single system prompt per conversation... but it turns out my recent redesign should handle that just fine.
Lower prompt cache minimum. The minimum cacheable prompt length on Claude Opus 4.8 is 1,024 tokens, lower than on Claude Opus 4.7.
I checked and 4.7’s minimum was 4,096.
And some pelicans
Here are pelicans riding bicycles for all five thinking levels, low, medium, high, xhigh, and max:
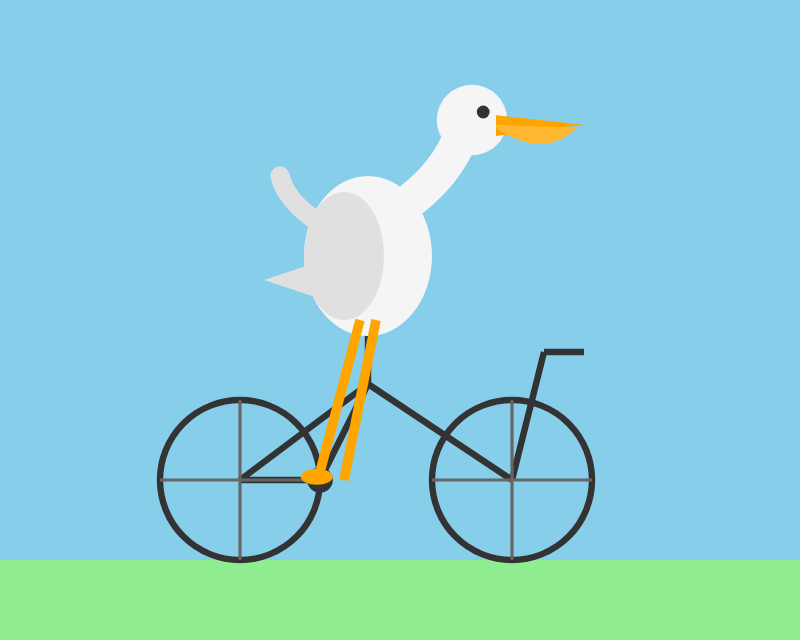
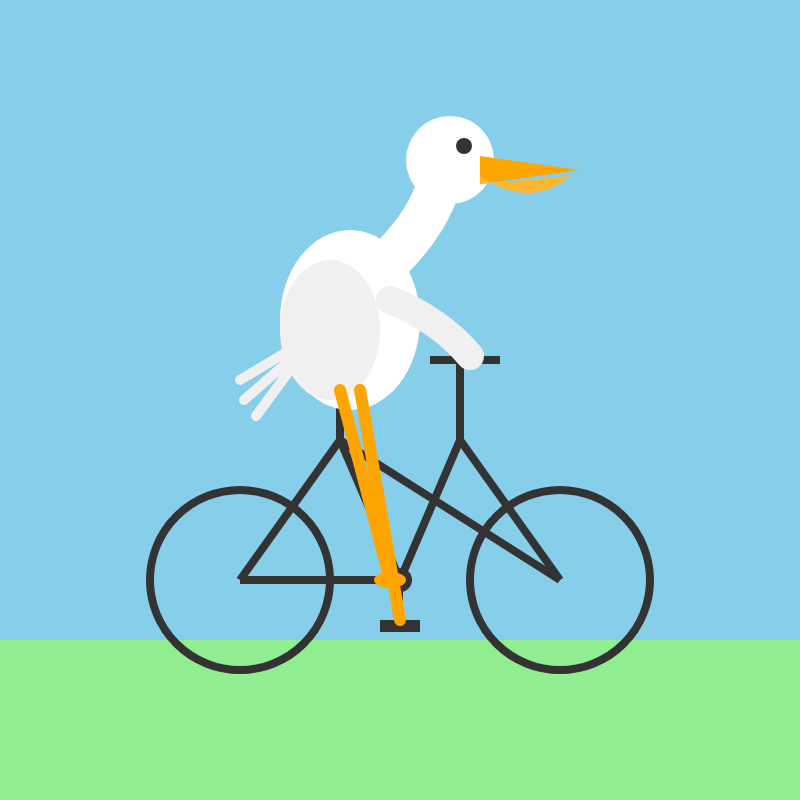
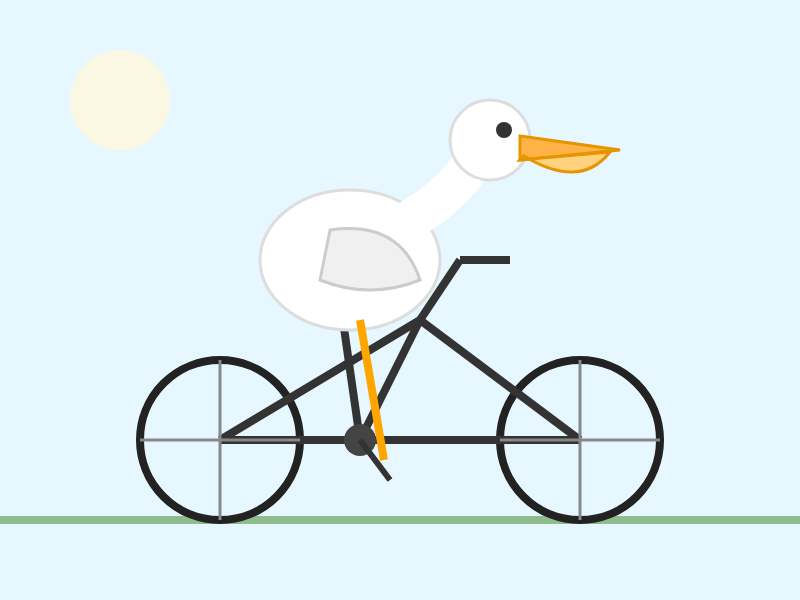
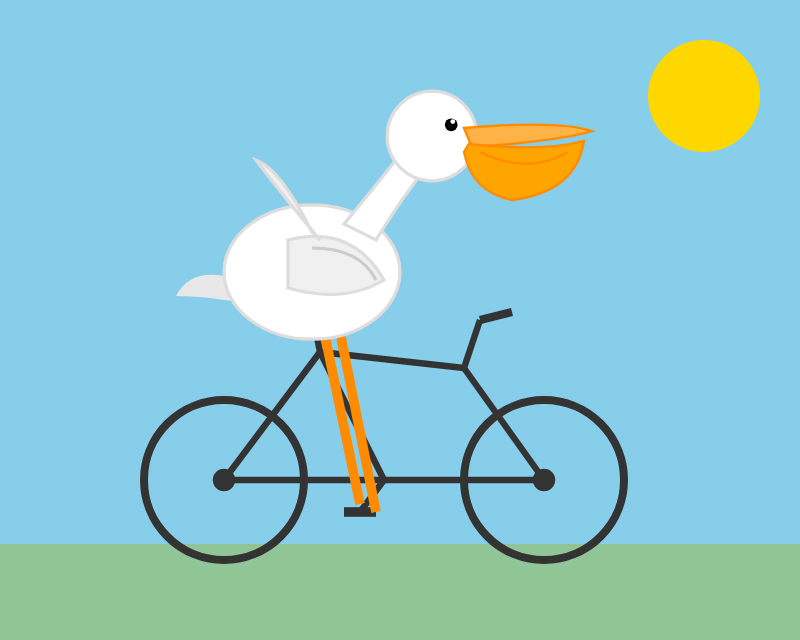
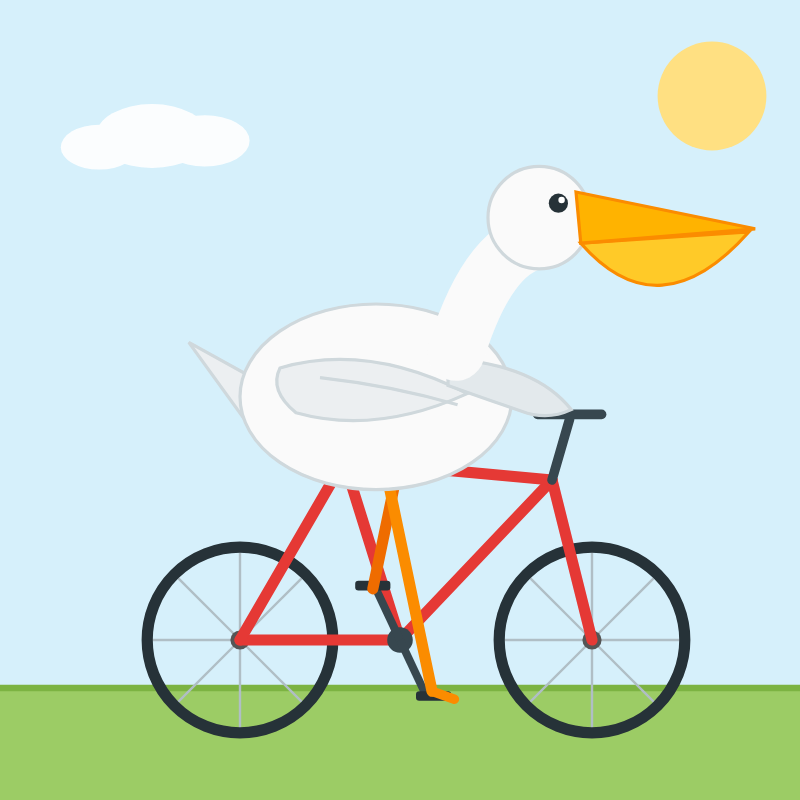
This time I ran them using the LLM CLI, exported the logs to Markdown and then had Claude Opus 4.8 build me an HTML tool that could render that Markdown with the svg fenced code blocks displayed as SVGs on the page.
(I later had GPT-5.5 xhigh in Codex update that code to remove any XSS holes. I’m sure Claude could have done that if I’d asked, but GPT-5.5 is my code security blanket at the moment.)
The max one was clearly the best, but it did take 25 input, 17,167 output tokens for a total cost of 43 cents!
More recent articles
- We're going to need default hard budget caps on pretty much everything - 3rd October 2026
- OpenAI DevDay 2026 live blog - 29th September 2026
- 2026 in LLMs (so far) - 27th September 2026
