Maximize your
AI coding outcomes
Observe what your AI produces, optimize your model routes and agent context, and govern how your software factory runs.
What happens inside Faros
Faros builds a live model of your engineering from the systems you already run, coding agents to CI/CD. It finds model routes and agent context best suited to your codebase, proves them on your own work, and enforces them at your gateway. So you ship production code faster and at lower cost.
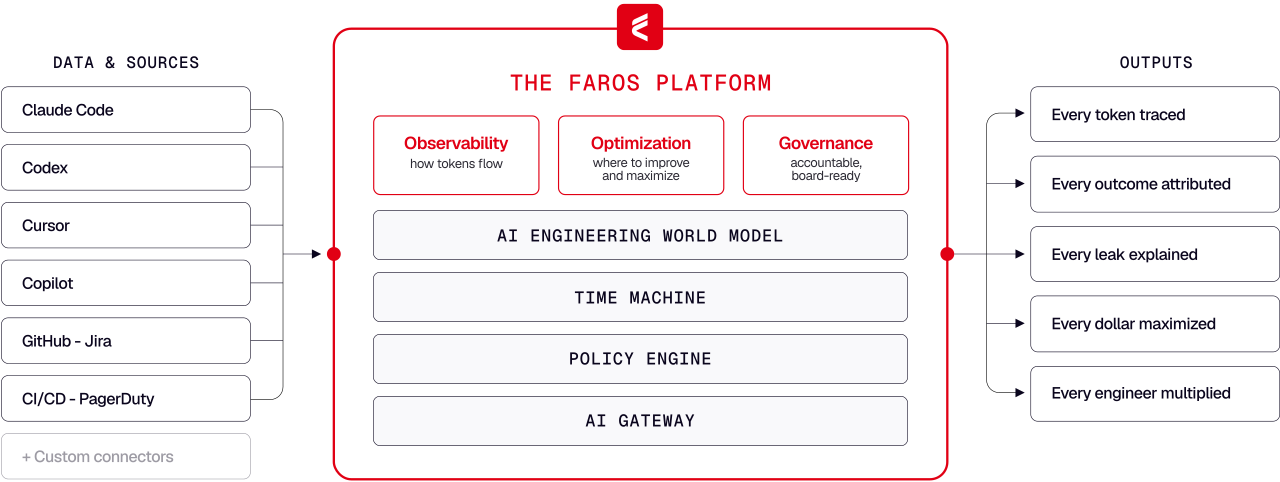
Engineering world model
Joins engineering semantics, operational data, and token flow into one live graph: tickets, agent sessions, commits, PRs, and CI verdicts. Attribution runs per session, per PR, per team, per model, and stays current as your tools change.
Time machine
An evidence-backed evaluation engine, built on your organization's own completed work, scoring every route against what actually shipped. Unlike public benchmarks, its results don't need to transfer to your codebase. They come from it.
Policy engine
Manages your policies across the organization, budgets and quotas, approved models, routing rules, and distributes them to your gateways and harnesses for enforcement while the factory runs. Every action lands in the audit trail.
Token intelligence across all your engineering teams
Faros ties token spend to sessions, PRs, teams, and outcomes. Token spend rolls up to answers instead of estimates. Connect Faros directly to your own AI agents so they can pull any data and build any dashboard your team needs.
Spend attribution
Ground every dollar of spend in real outcomes. Instantly see which models and projects are earning their cost.
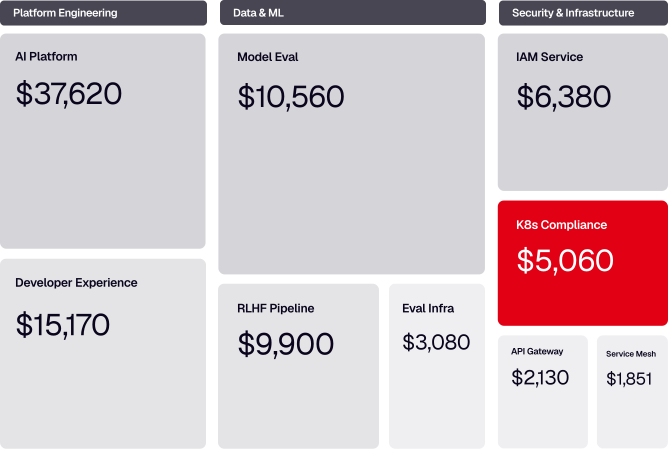
Efficiency benchmarking
See every team’s efficiency and strategic importance in one view, sized by spend, so you know what to protect and scale, hold steady, fix, or cut back.
Engineering metrics
All of your developer productivity metrics in one queryable graph. Connect your agents so they can build any dashboard your team needs.
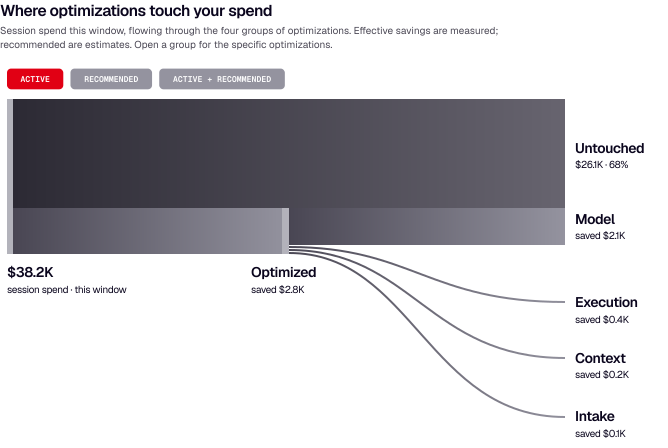
Raise agent output , proven on your own work
Faros doesn't stop at showing you the leaks. It mines your history for the highest-ROI model routes, agent context, and workflow fixes, verifies each one with the Time Machine, and delivers it ready to apply.
Model routings
Implement optimal model routes that work best in your environment, derived from your own engineering work.
Context engineering
Connect your agents to Faros to give them the full context of your repo-specific skills, and rules, supercharging their planning and execution.
SDLC discoveries
Neutralize efficiency bottlenecks via findings specific to your AI Engineering environment.
Guardrails that minimize risk as you grow
Optimization scales only if it's governed. Faros keeps your organization inside its guardrails as usage increases, with policies enforced while work happens.
Budgets & quotas
Ensure compliance with your team-specific usage policies.
AI risk & guardrails
Define which models, harnesses, and configurations each team is allowed to use, and keep every choice within policy.
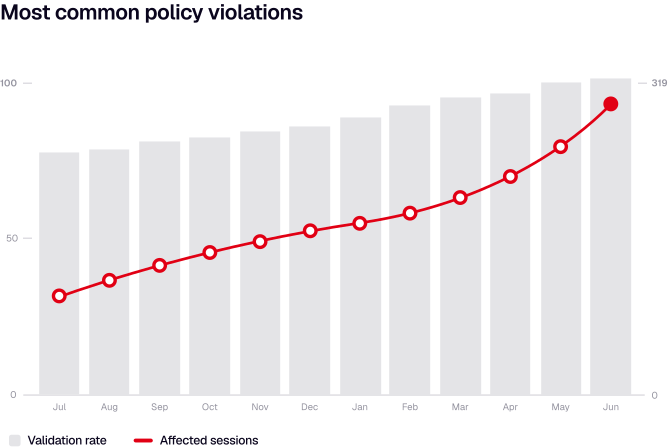
Violation monitoring
See which teams are violating budget, quota, or risk policies.
Auditability
Tie every shipped change back to the spend, model, agent, and context that produced it.
Designed and built for AI Engineering
Grounded in your engineering context, Faros is the only closed-loop system that maximizes engineering outcomes without locking you into any model or provider.
Unlike coding harnesses or standalone models
Faros works across arbitrarily heterogeneous environments of harnesses and models.
Unlike AI gateways
Faros optimizes AI workflows based on your specific engineering context and works with any router - yours or ours.
Unlike developer productivity tools
Faros optimizes how your agents work inside engineering environments, instead of developers.
Unlike FinOps tools
Faros goes beyond cost reporting to optimize AI workflows inside engineering environments.
Connects with everything AI engineering
Faros works by connecting to the systems where AI coding work already lives, from builder desktops and agents to gateways, source control, tickets, CI/CD pipelines, and incidents.




Stop token maxxing.
Start outcome maxxing.
Run it live in your own org. Work with us to measure what your AI coding ships, and determine which models work best on your codebase.
Enterprise-grade security
Faros is built to enterprise-grade standards and is SOC 2 Type II, ISO 27001, and GDPR compliant. Your data never leaves your boundary. Learn more about security practices.



What engineering leaders are asking us
Every engineering leader arrives with a different question. These are the ones we hear most.
Three outcome signals. Eleven guardrail metrics.
One framework for running AI spend.
Get a teardown of your last 30 days. Every token traced to the outcome it shipped, and the models your work actually needs.
